Explaining a Production Incident to Non-Technical Stakeholders
Assign separate roles to keep incident response from drowning in stakeholder questions.
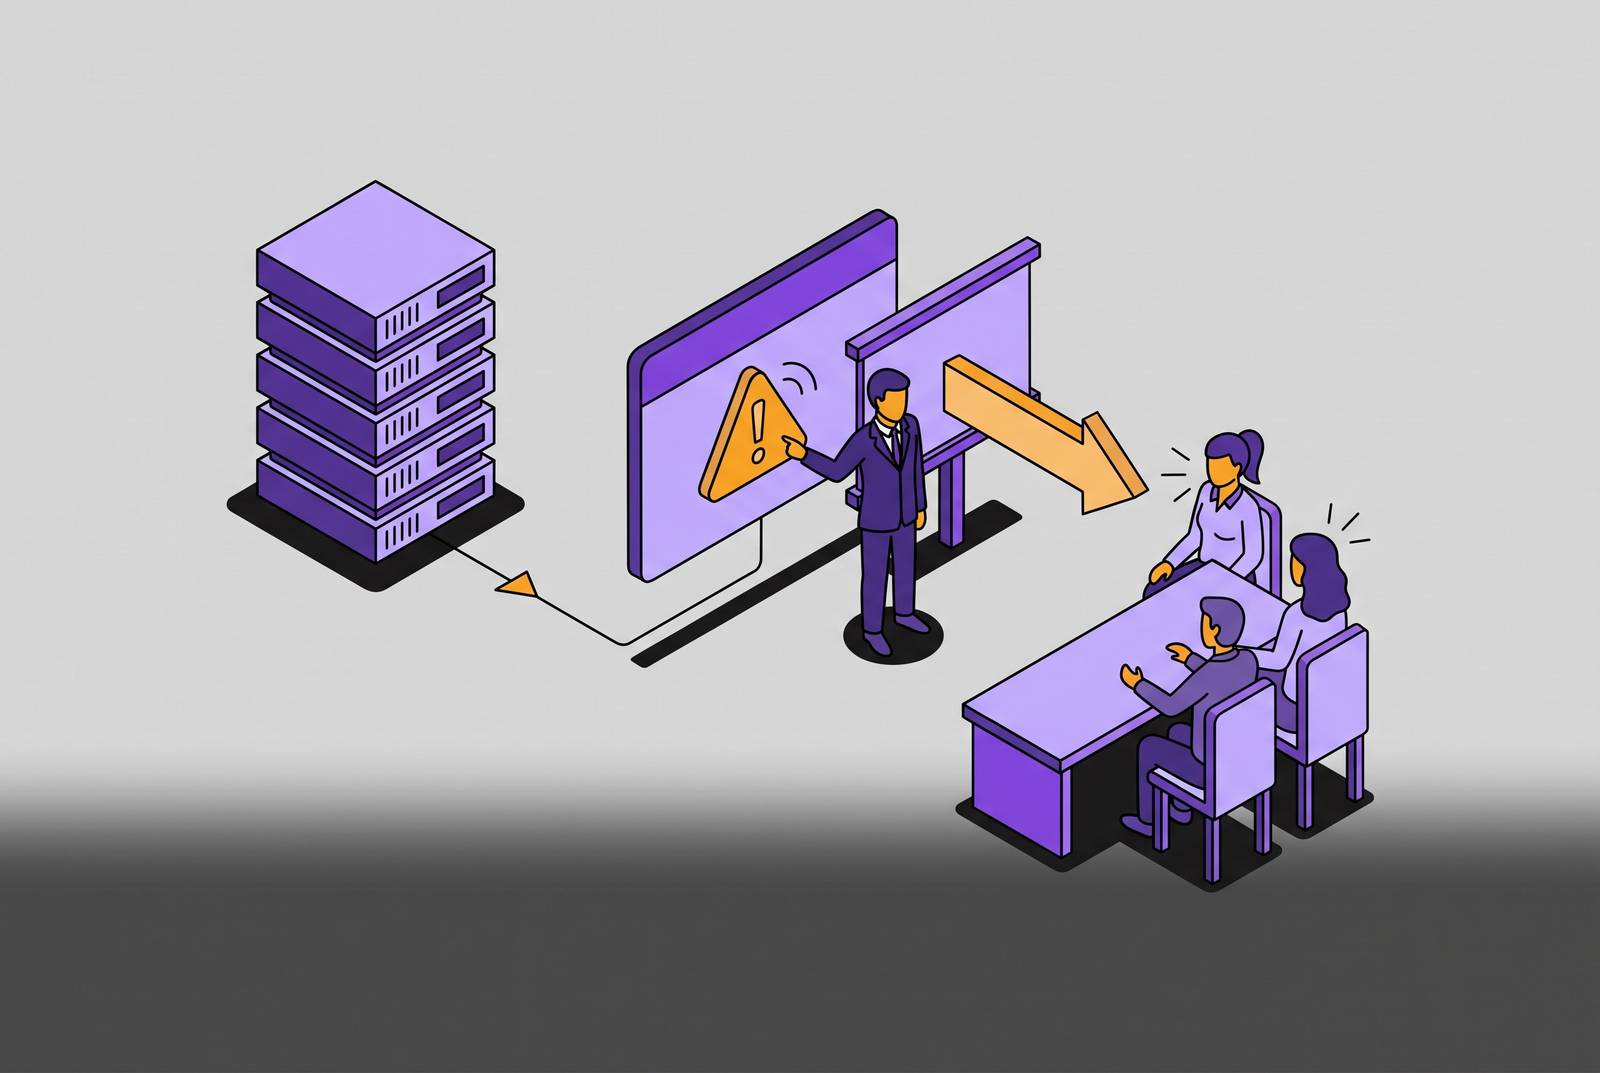
Explaining a production incident to non-technical stakeholders requires a response track separate from the work of restoring service. The discipline is to translate a shared set of facts for different audiences, assign clear ownership, and communicate on a practiced schedule. Without that structure, stakeholder questions compete with diagnosis, and communication becomes a second crisis.
Why explaining an incident is a different job from fixing one
Technical response and stakeholder communication produce different outputs. Responders establish what failed and how to restore service, while the communication function explains impact, uncertainty, and progress in terms its readers can use. Neither output follows automatically from the other. An engineer may understand a failure well enough to mitigate it without having time to draft a useful executive update.
The common failure is collision rather than simple neglect. The same people diagnose the incident, answer leadership questions, and compose external messages, so every writing task interrupts technical work. A separate communications lead removes that competition for attention. The person in this role needs to be ready and have the authority to act, as well as be willing to help when the response gets busy.
What silence costs and why the first update must go out before the cause is known
Customers cannot distinguish an unexplained outage from an unmanaged one. Without updates, stakeholders guess at what is happening and often imagine it is worse than the known impact. Atlassian’s incident communication guide says that customers who know what is happening react less negatively and are less likely to leave. Early acknowledgment is therefore responsible disclosure of the current situation.
A claim that later needs correction can damage trust, particularly when it names a cause or promises a restoration time. The first update should instead state the observed impact, the investigation status, and the next update time. Those are different commitments from a diagnosis. An unconfirmed resolution ETA makes a promise the response team may not be able to keep, while a scheduled update commits only to communication.
How different audiences need different versions of the same truth
Engineers need current impact, suspected scope, a mitigation owner, the next checkpoint, and any help required. Executives need severity, known customer or revenue exposure, escalation needs, communication risk, and confidence in the assessment. Conversely, an outcome-focused executive summary will not give responders enough context to coordinate their work.
Support and customer success need bounded language they can relay without overpromising, including what users may experience and whether a workaround exists. Customers need the affected service area, the practical effect, any workaround, and the next update time. The translation can be direct. An engineering update may describe elevated p99 latency due to a cascading failure in the service mesh, while the customer version says, “Users may experience slow load times or failed requests”. Both versions must draw from one shared source of truth, with detail selected for the decision each reader needs to make.
The three roles that must be assigned before an incident starts
Undefined ownership leaves communication to whoever has a free moment. During an incident, that is rarely anyone. The Incident Commander holds final approval authority for external communication and sets the update cadence, but does not draft updates. On SEV1 and SEV2 incidents, nothing goes out without IC sign-off. This separates the decision about what can be said from the work of writing and distributing it.
The Communications Lead drafts, owns, and sends internal and external updates, including the resolution announcement and post-incident follow-up. The Scribe maintains a timestamped record of actions, decisions, and messages that becomes the basis of the blameless postmortem. Small teams may combine the communications and IC functions, while teams with fewer than six engineers often combine communications and scribing. Those combinations have limits. Combining scribing and communications may work for short incidents but creates risk beyond two hours.
Responders need a technical war room, while leadership needs a broadcast channel where messages go out without discussion. Merging them increases noise and slows decisions. Security incidents also require coordinated CISO or CIO updates, with legal counsel involved in board-level communication from the start.
Separating severity, scope, and confidence in every update
A phrase such as “major issue” compresses several judgments into one ambiguous label. Severity describes operational seriousness, scope identifies the affected service, feature, region, or users, and confidence states how certain the assessment is. These fields answer different questions. Keeping them separate prevents an early estimate of reach from becoming an unqualified public claim.
For example, “high-impact checkout issue” leaves readers to infer both reach and certainty. A more useful assessment gives the assigned severity tier, states that some customers cannot complete checkout, and marks confidence as medium based on queue backlog and support tickets, with the full scope still under investigation. The uncertainty remains visible. It does not have to be hidden inside a vague adjective.
The same boundary applies to causal claims. “A database issue is causing checkout failures” requires evidence that an acknowledgment of checkout failures does not. Separate fields for “Confirmed facts” and “Working hypothesis, internal only” keep that distinction explicit. An external update can report that some customers cannot complete checkout, that the cause is under investigation, and that another update will arrive by 14:30 UTC without publishing the internal hypothesis.
How update cadence prevents the interrupt tax from falling on engineers
When stakeholders have to ask for every update, responders have to spend time answering them. Repeated pings interrupt diagnosis and indicate that the existing process is not trusted to provide information. A required “Next update by” field lets readers know when to expect another message.
High-severity incidents need short updates often, lower-severity incidents need updates at times readers can count on, and resolved incidents need a closing message. Updates are still due at the promised interval even when the team does not yet know the cause. This structure protects the focus needed for mitigation, because engineers who context-switch to answer questions take longer to resolve problems and are more likely to miss something. Cadence is therefore a lever on mean time to resolution.
What to say — and not say — at each stage of the incident lifecycle
Acknowledgment should go out within 15 minutes of detection. It states that an issue is known, describes what users may experience, notes that investigation is underway, and gives the next update time. The cause can remain unknown at this stage. The message should not speculate about root cause, offer an unsupported resolution ETA, or imply that the problem is smaller than the available evidence suggests.
During the active response, updates go out at every promised interval. They report changes in scope, the current mitigation action and its owner where relevant to the audience, the confidence level, and the next update time. Audience boundaries still apply during this stage. An internal coordination message can name the mitigation owner, while a customer update should omit unconfirmed hypotheses and infrastructure names that do not help the reader. A vague reassurance that work continues is not a substitute for useful status.
A resolution message needs evidence that service is restored and stable. It should state that service is restored, describe what users experienced, and explain the fix without exposing implementation detail. “Everything is back to normal” is premature before stability has been established. Nor should the announcement describe the incident as trivial when customers were visibly affected. The message closes the live response without minimizing its consequences.
Post-incident communication then explains the cause at a high level, what restored service, and what safeguards or changes were put in place. Customers who noticed the incident deserve specific prevention actions. The scribe’s record provides the factual backbone for this account. Its purpose is to make the response legible and credible.
Where the speed-vs.-accuracy tension actually lives and how to resolve it
Templates can mislead when an incident does not fit their assumptions. Language prepared for a routine partial outage may understate a data exposure or overstate a minor degradation. Structure does not remove that risk by itself. Its alternative, however, cannot be several people publishing independent explanations that leave support, leadership, engineering, and customers with different versions of events.
The IC has the authority to approve messages so they can judge whether the prepared language fits the incident. Confidence fields and clear statements that scope is still under investigation let the team give useful details without claiming more certainty than it has. Engineering or SRE owns communication for operational incidents with a limited duration, while executives must own communication for high-impact crises that threaten reputation, with legal involved. Recognizing that shift is a judgment call that no template can make on its own.
How the complexity of modern codebases makes the communication gap harder to close
A shared account is harder to build when no single engineer understands the whole system. Distributed services, multi-repository codebases, and AI-assisted development make it more difficult to establish what changed, what depends on what, and what is broken. Investigation consumes most of the resolution time in complex-codebase environments. The communications lead cannot translate facts that responders have not yet established.
Without cross-repository search and navigation, engineers reconstruct the picture across log consoles, alerting platforms, version control, and issue trackers. Each context switch delays the next accurate account. An AI coding agent limited to locally available files faces the same constraint when asked what changed upstream. Full codebase context, including dependency graphs and recent change history, helps engineers and agents investigate those connections, shortening the period in which stakeholder updates must remain bounded by incomplete information.
What self-hosted code intelligence infrastructure contributes to faster, more accurate incident communication
A code intelligence platform can make every repository searchable through a prebuilt index, including through natural-language queries. Instead of reconstructing dependencies and recent changes across eight or more tools, an on-call responder can query a shared code search layer. This shortens the investigative path to a useful explanation. Getting those facts faster gives the communications lead accurate details sooner, though the first acknowledgment still has to go out before the investigation is complete.
Systems that break, dependencies that fail, and configuration that is wrong can expose sensitive parts of a codebase. Sending that context to an external model or SaaS tool raises data-boundary questions that are difficult to settle under pressure. A self-hosted search layer keeps that context from the investigation within the team’s hosting boundary.
Natural-language access can also reduce routine interruptions from non-engineers. Support leads, customer success managers, and PMs can query codebase context instead of asking a senior engineer to find it for them. That access helps with the investigation, while messages still need approval. AI coding agents connected to full-codebase context through MCP can find recent changes, trace dependency chains, and flag risky areas, so responders do not have to piece together the same picture by hand across tools.
Building the communication habit before the incident happens
Preparation gives the structure a chance to work. Atlassian’s guide recommends deciding what counts as an incident, choosing channels and templates ahead of time, and setting up a zero-tolerance communication plan for security issues or data loss. The escalation chain also needs to exist before the alert. These decisions are difficult to make reliably while the same team is trying to restore production.
A tabletop exercise can expose unclear ownership and give the communications lead practice drafting for an executive audience with incomplete information and a 60-second window. Repetition helps the team use its structure under pressure.
The minimum viable structure can begin this week. Assign the Incident Commander, Communications Lead, and Scribe, define severity levels, and build internal and external template variants for each severity tier. Then rehearse an incident with those roles and templates, with the communications lead writing updates to meet the agreed schedule.